Is the new prompt actually better?
JustEvals puts your eval runs side by side, so you see whether a model or prompt change made the output better. Your coding agent reads your picks and notes before the next change.
- Good
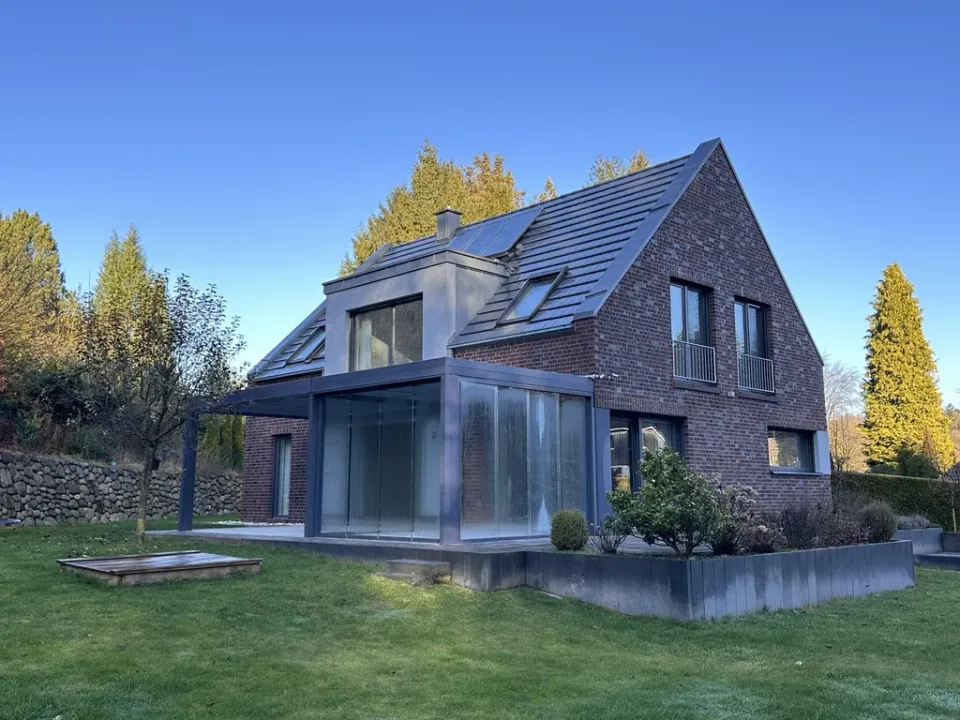
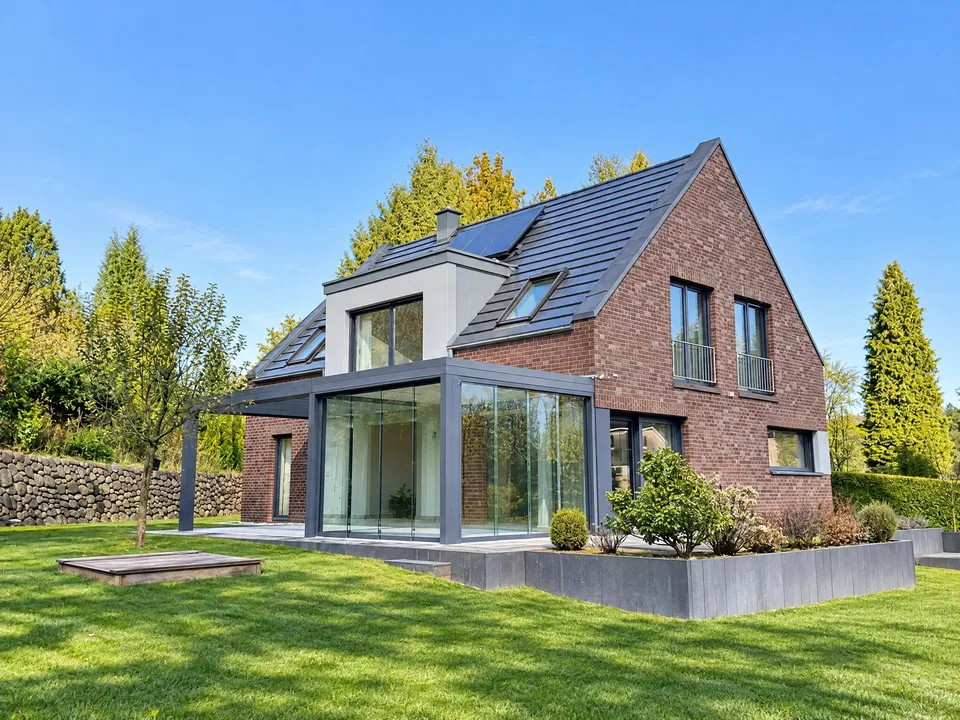
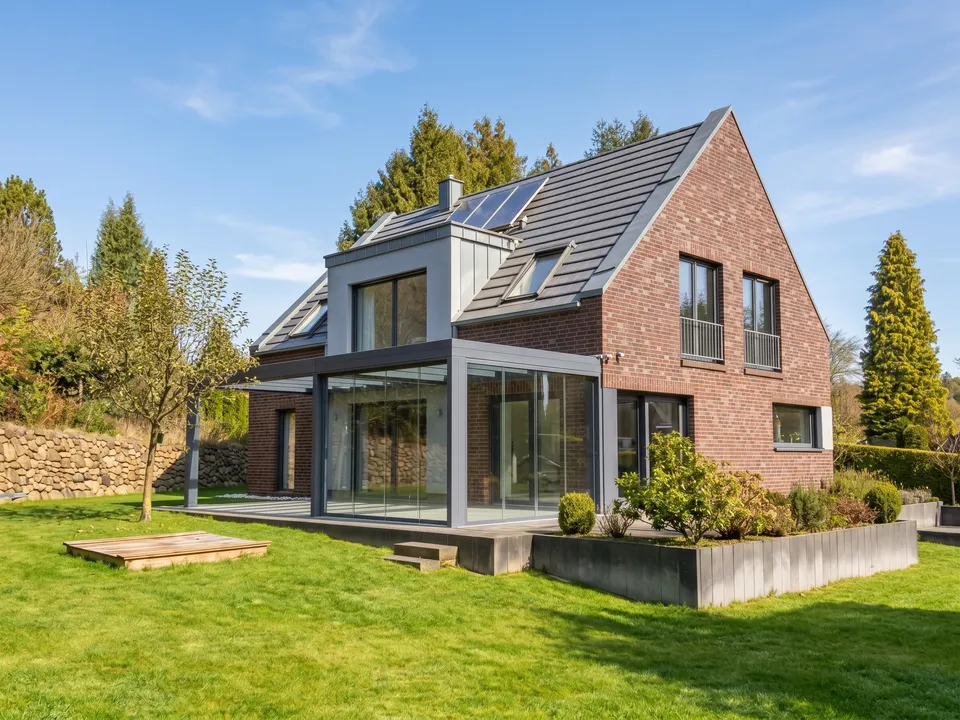
- Brighter, sunnier, cleaner, listing-ready exterior.
- Fails if
- Any window, door, roof or composition changes.
How does it work?
JustEvals never calls a model. Your pipeline keeps running the models and uploads what came out. People compare the results in JustEvals, and your coding agent reads what they decided.
Your pipeline
Runs the suite with your own code and keys, then uploads outputs, cost, latency and scores with one command.
$ python justevals.py push \ manifest.jsonuploadJustEvals
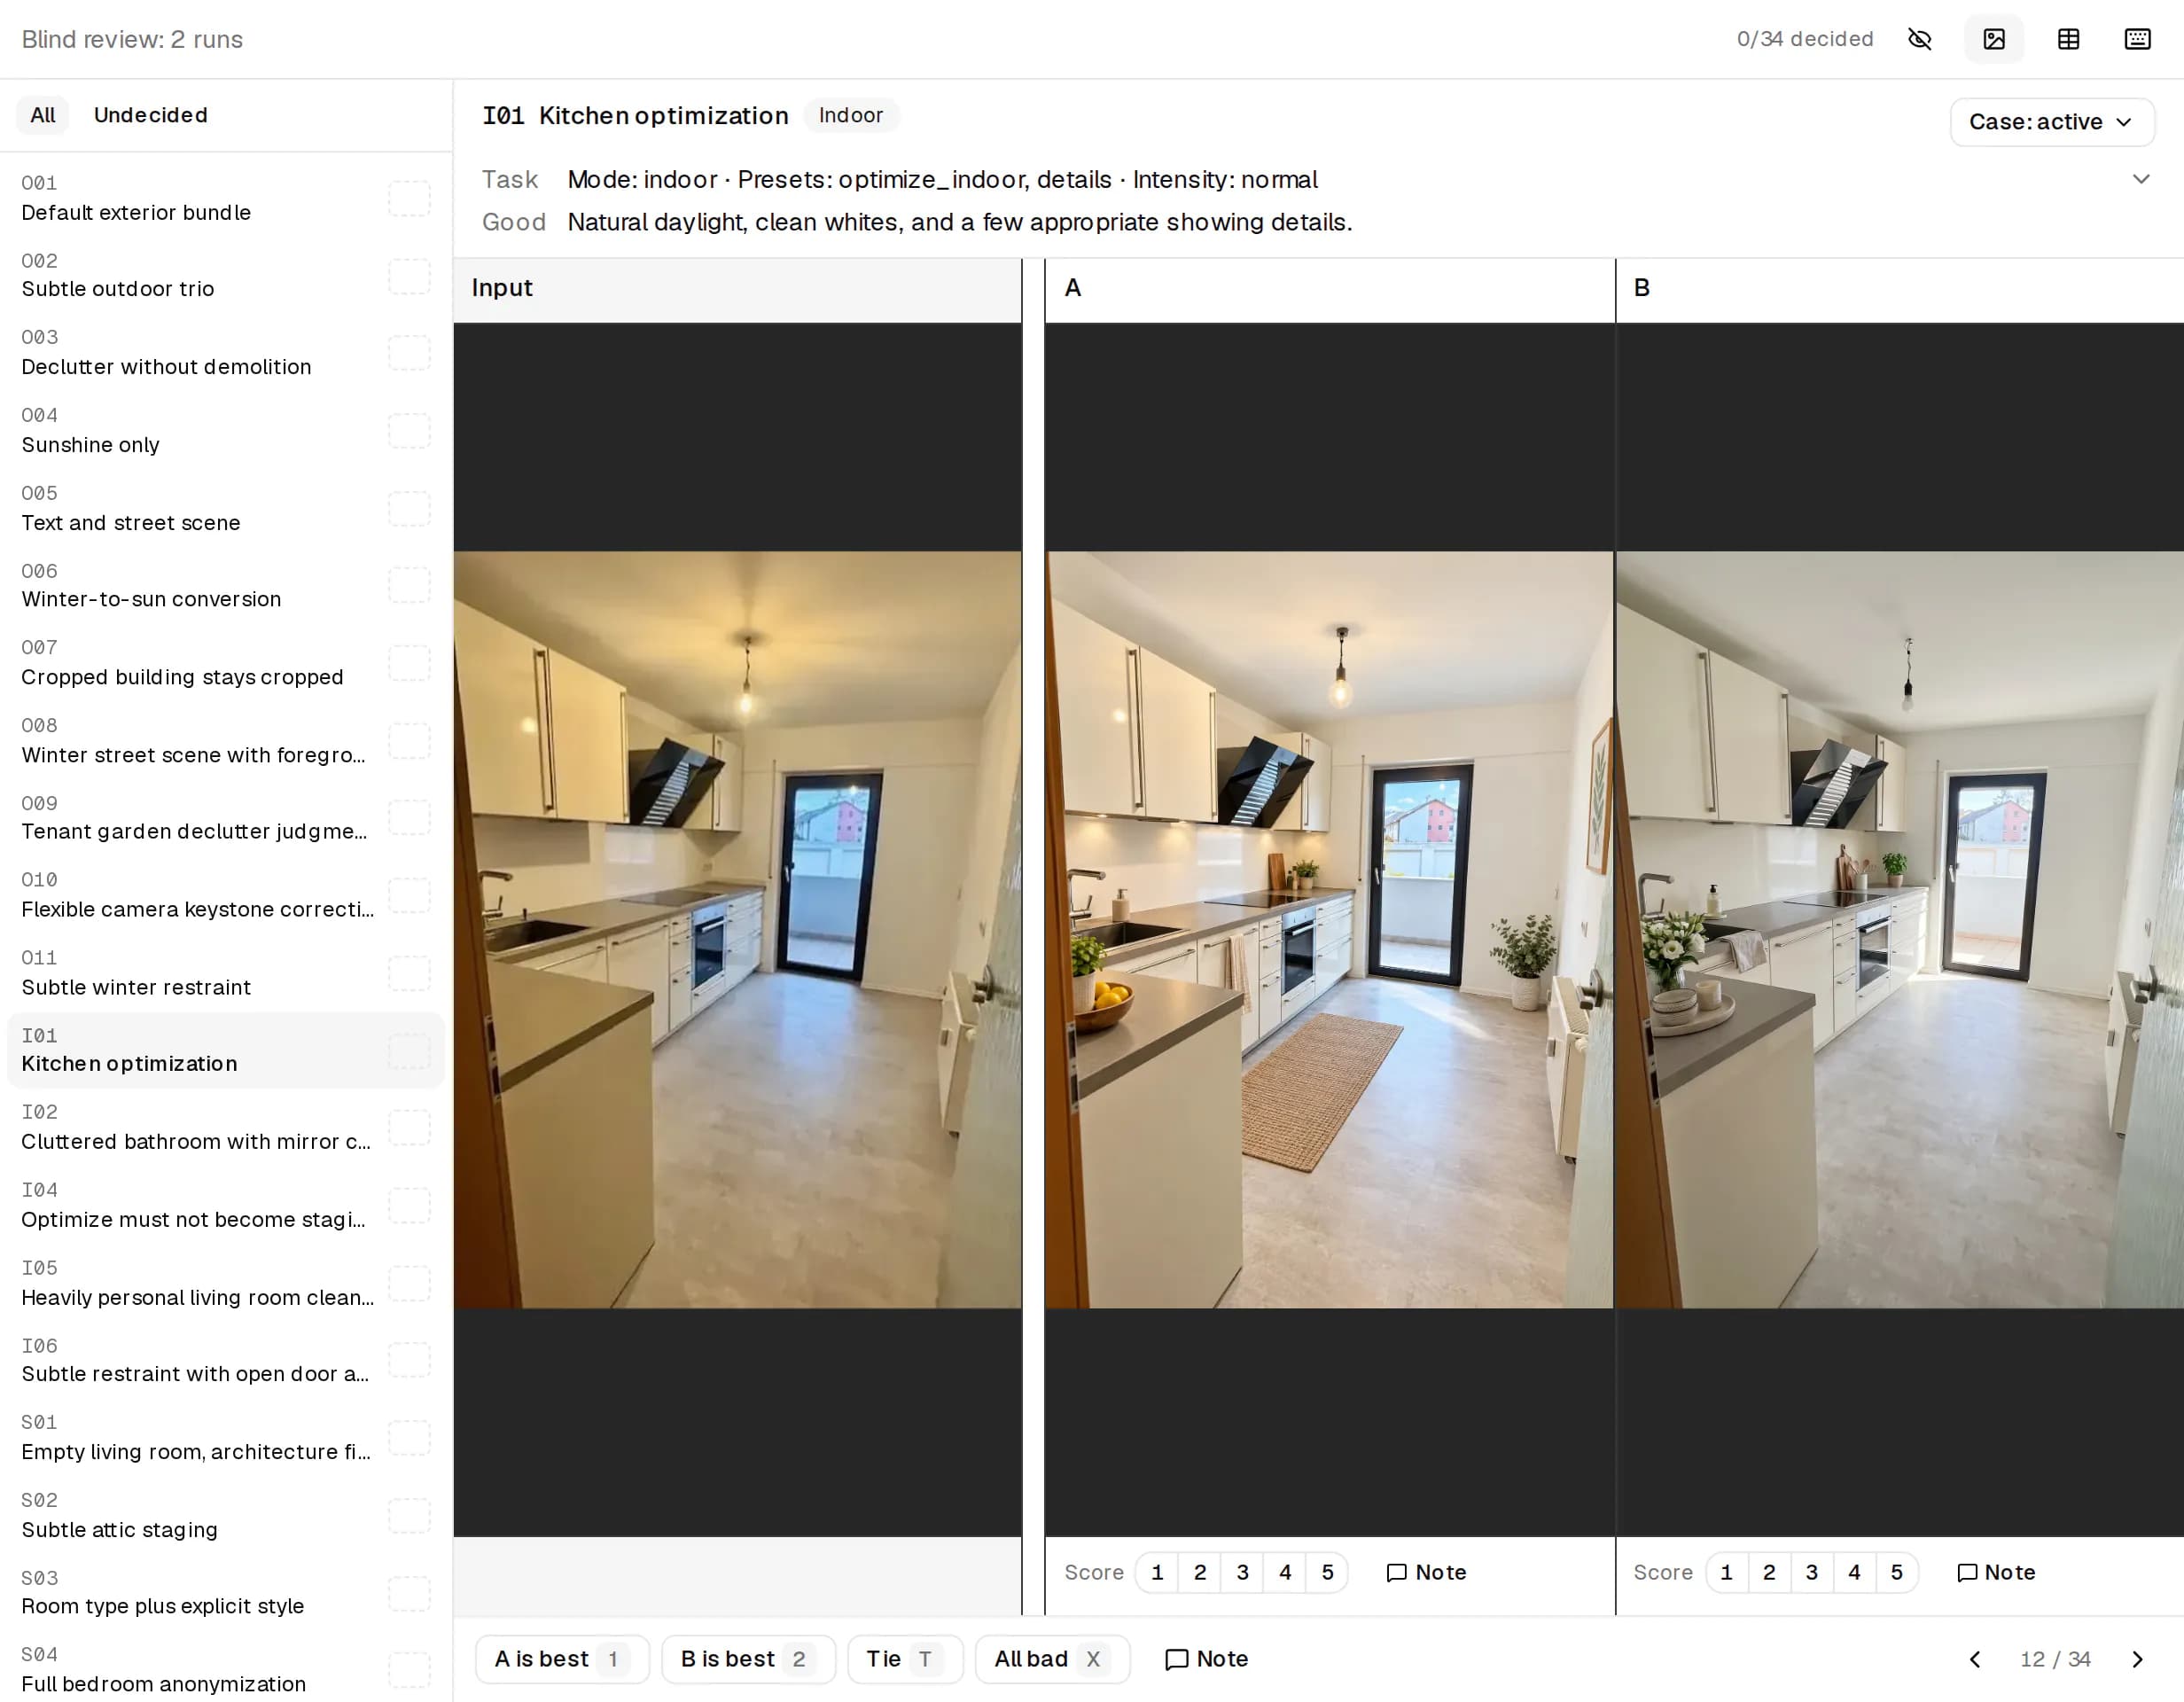
You pick the better output per case with the model names hidden. The eval shows which run won.
A 1B 2Tie TFlip SpacefeedbackYour coding agent
Reads the picks, ratings and notes, changes the prompt or the model, and runs the suite again.
$ python justevals.py feedback \
    --suite exterior
Every eval decision in one place
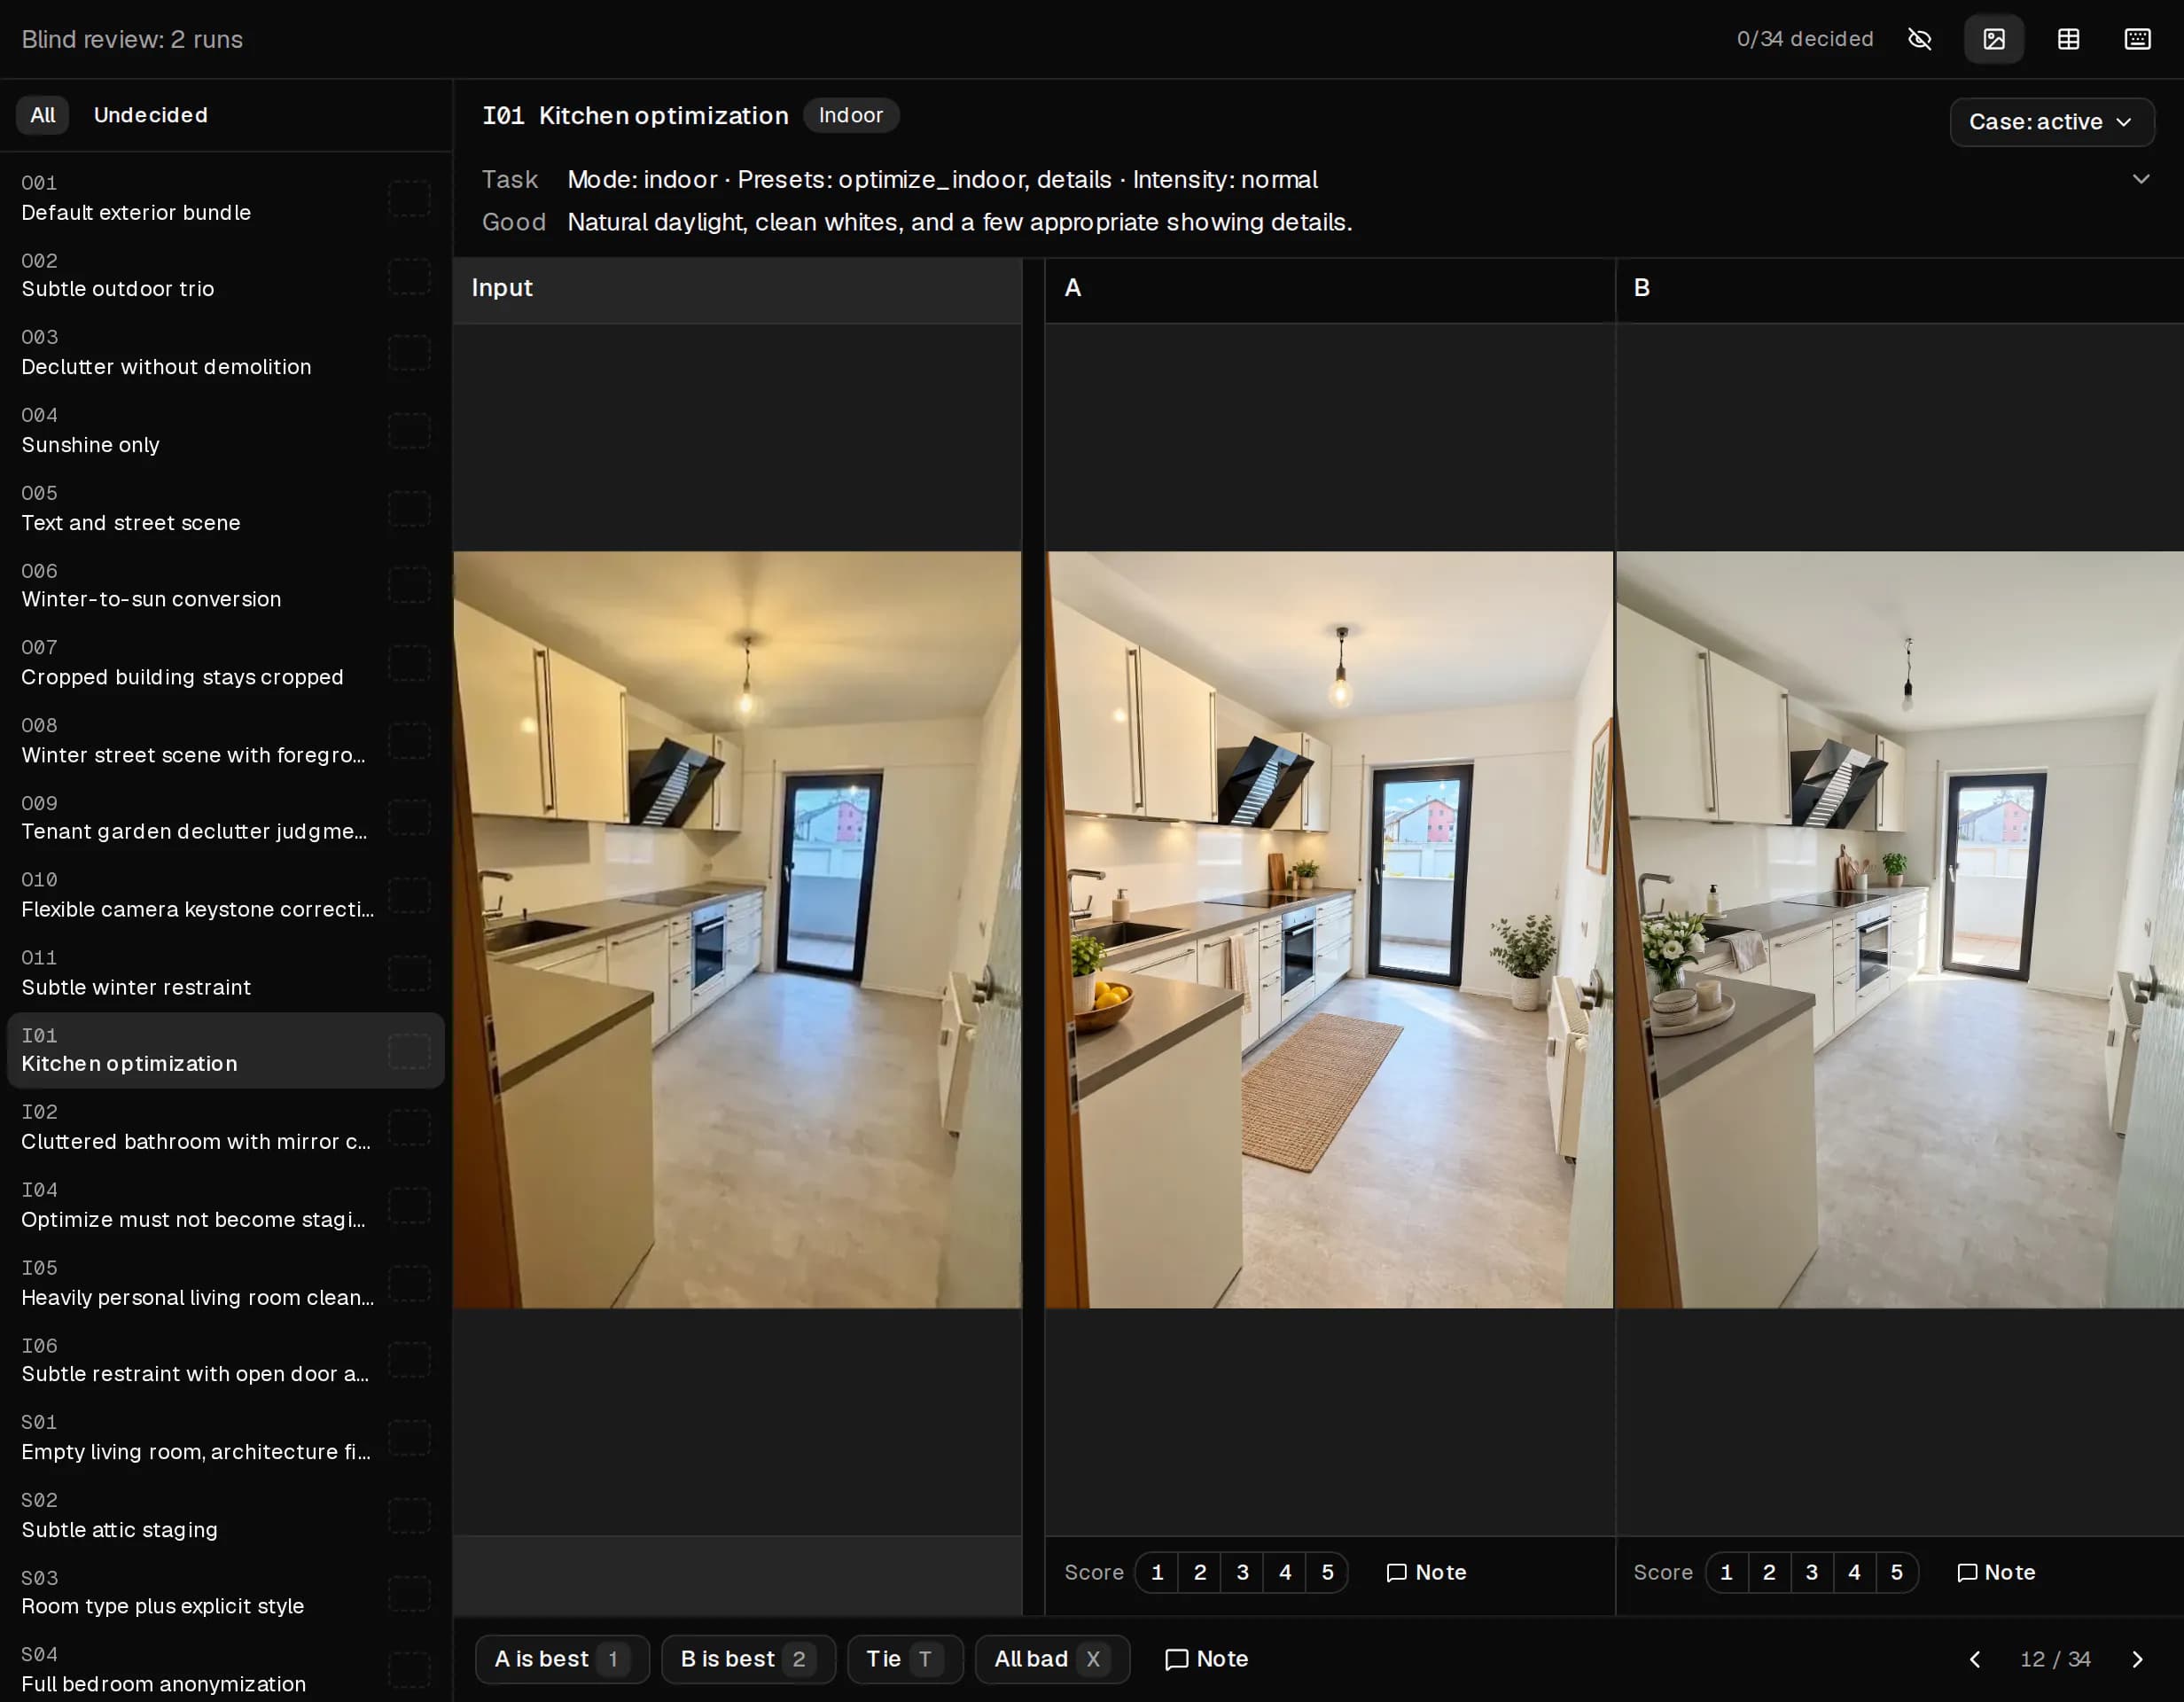
Pick the better output
Outputs change order per case, and run names stay hidden until you show them. Zoom follows across all images, and holding Space flips between them in place.
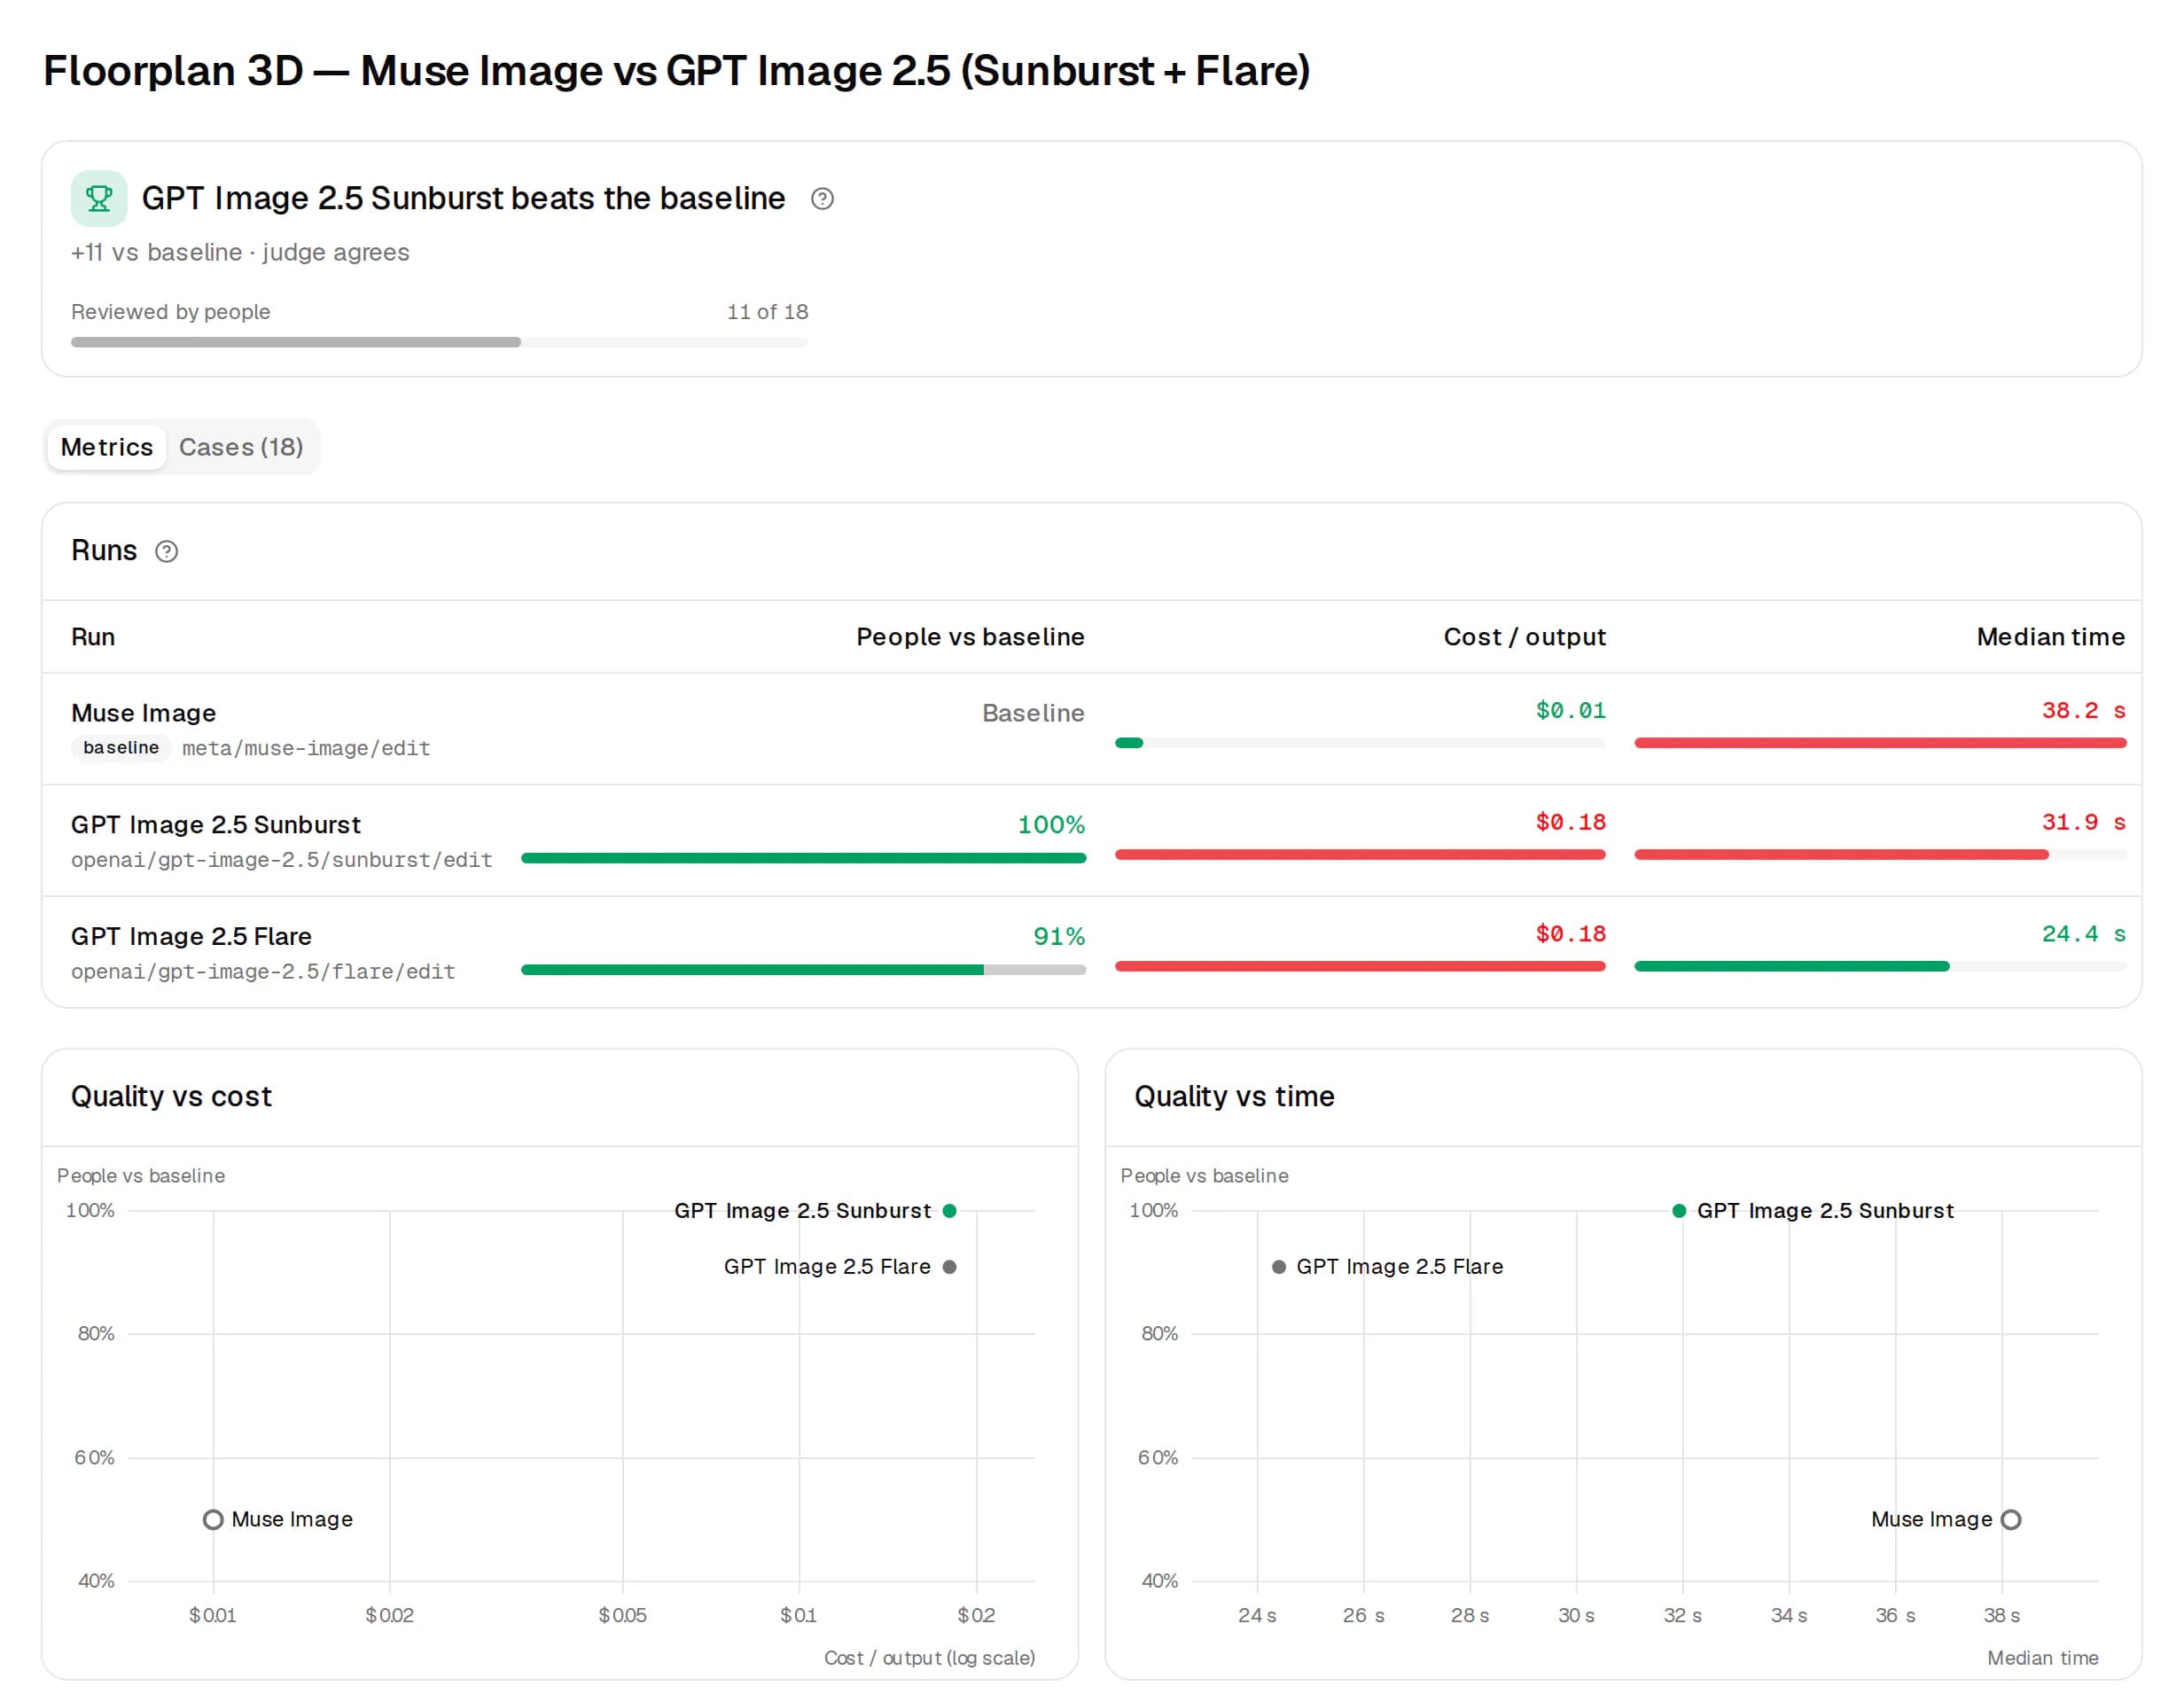
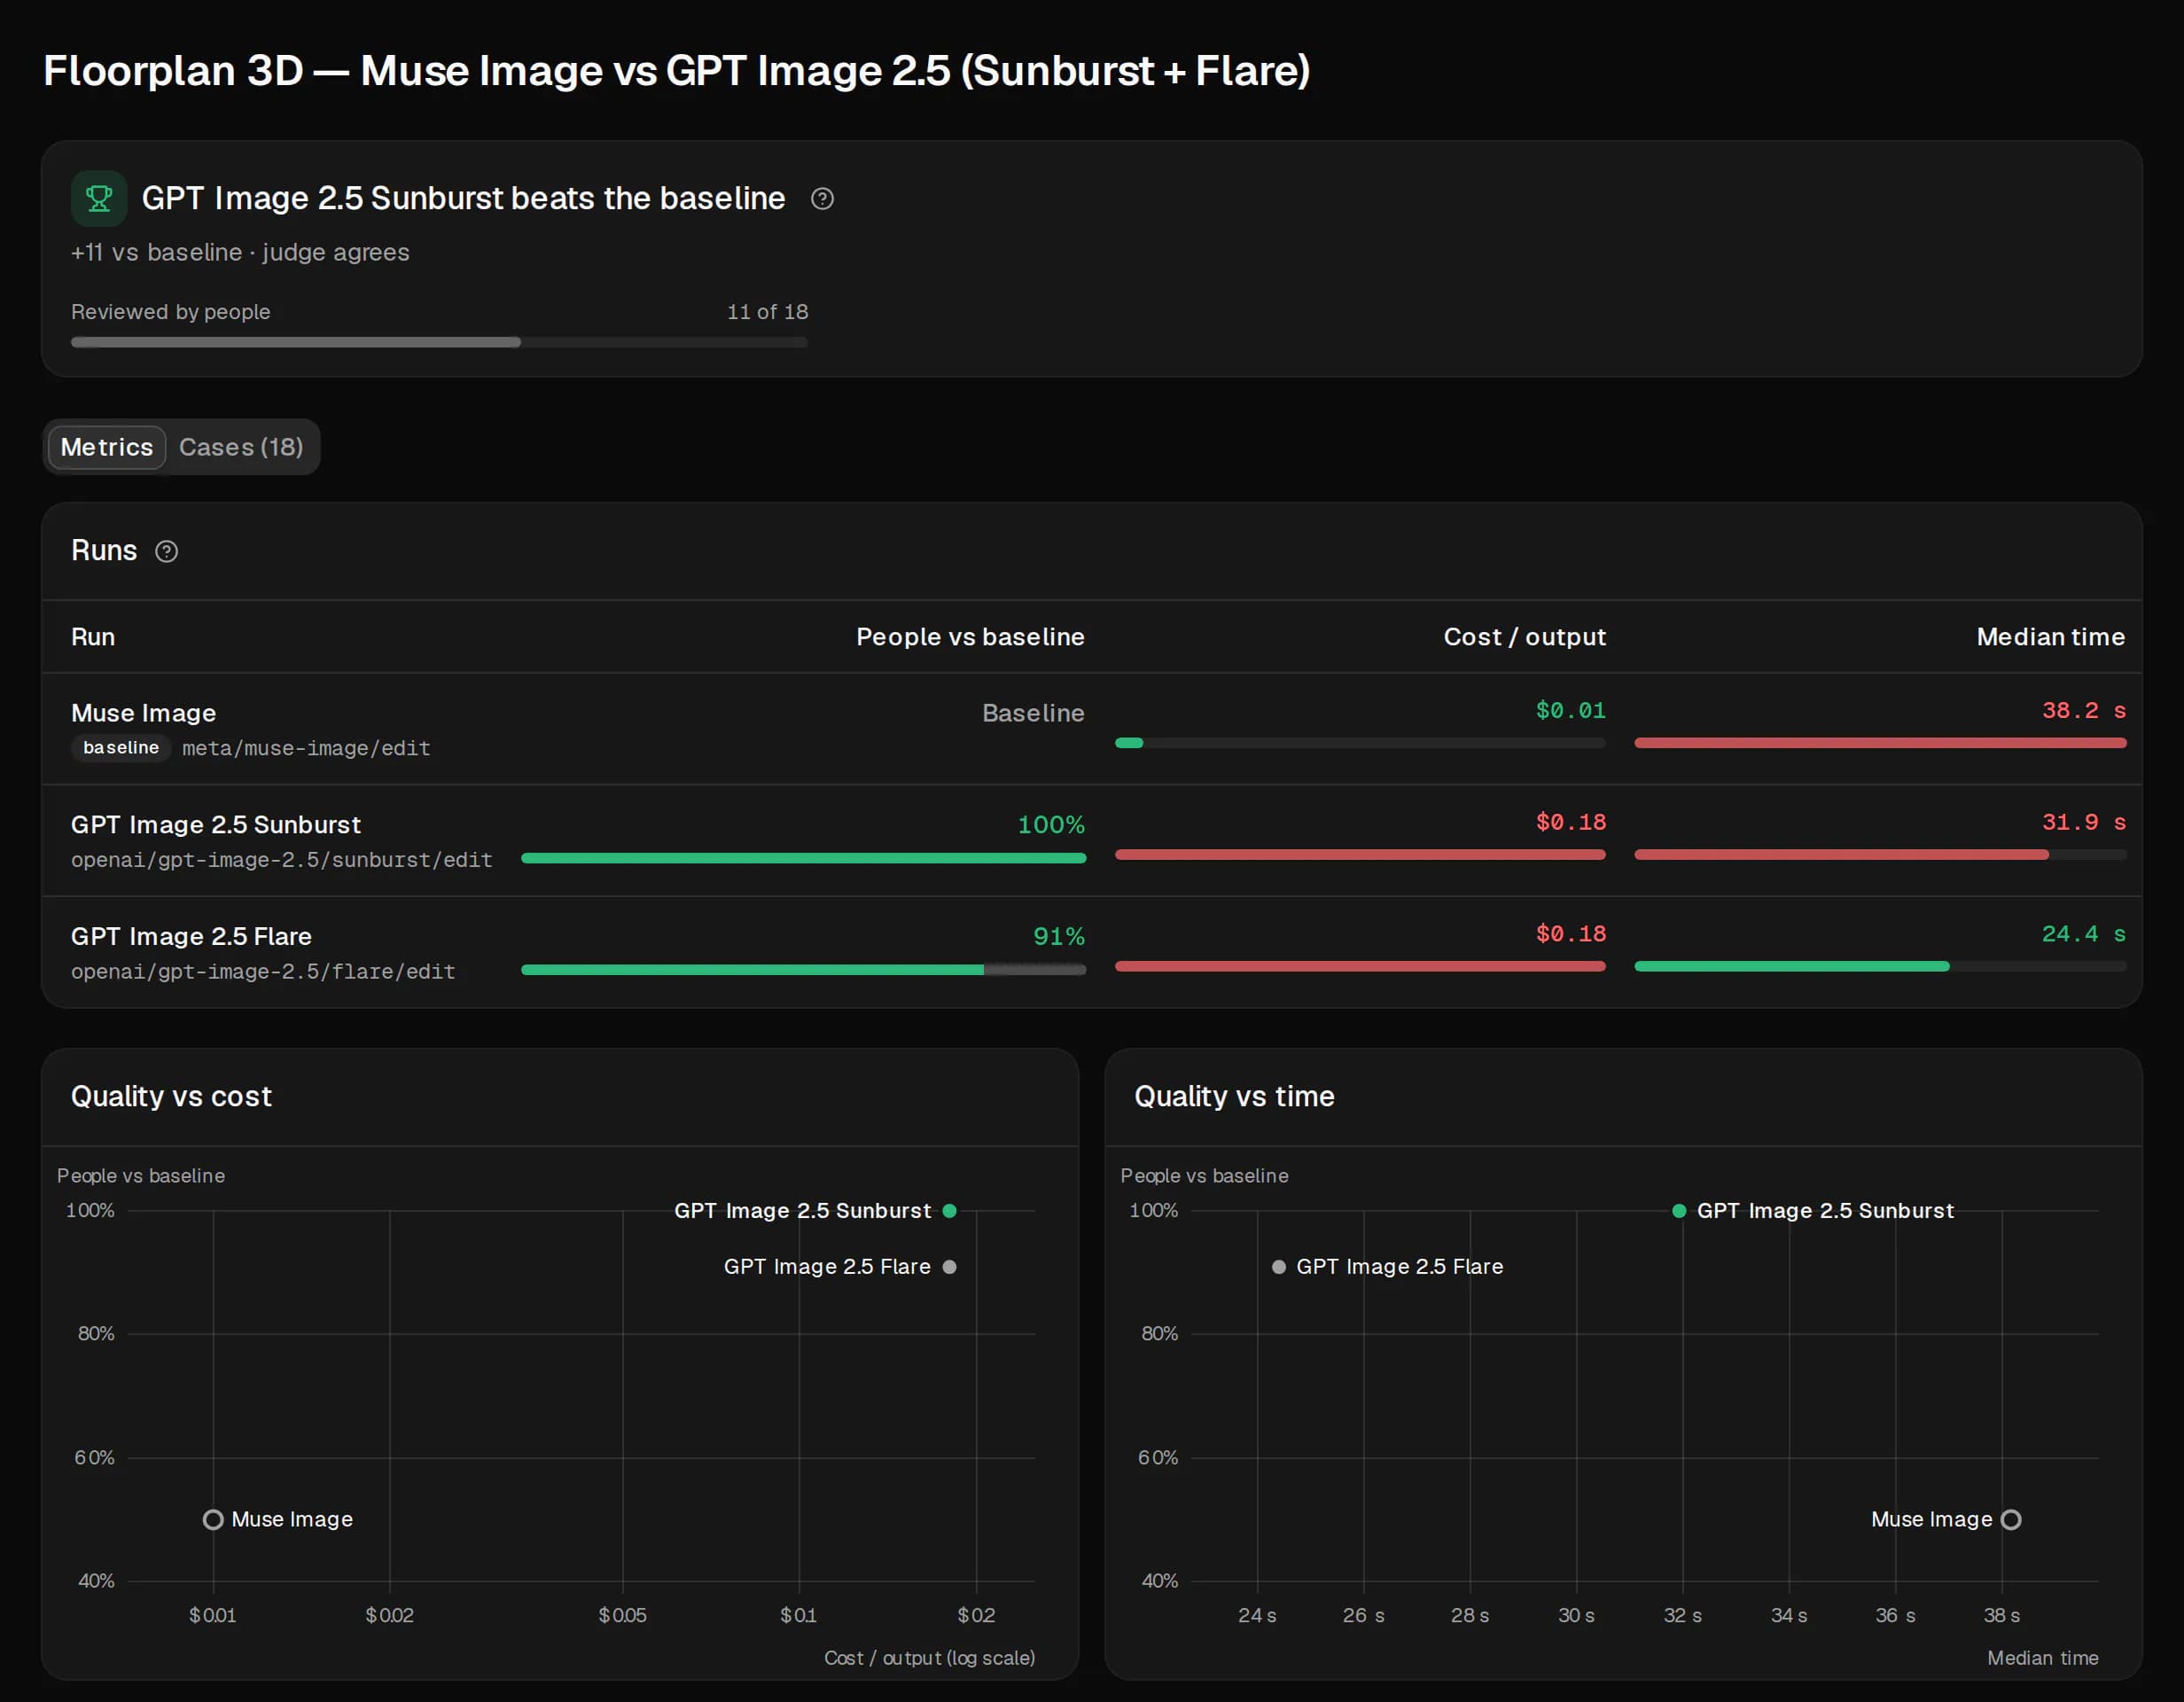
See which run won
Each eval shows the winner on your main metric next to cost per output and median time, and plots it against both. A winner that does worse on another metric gets flagged.
Check every case
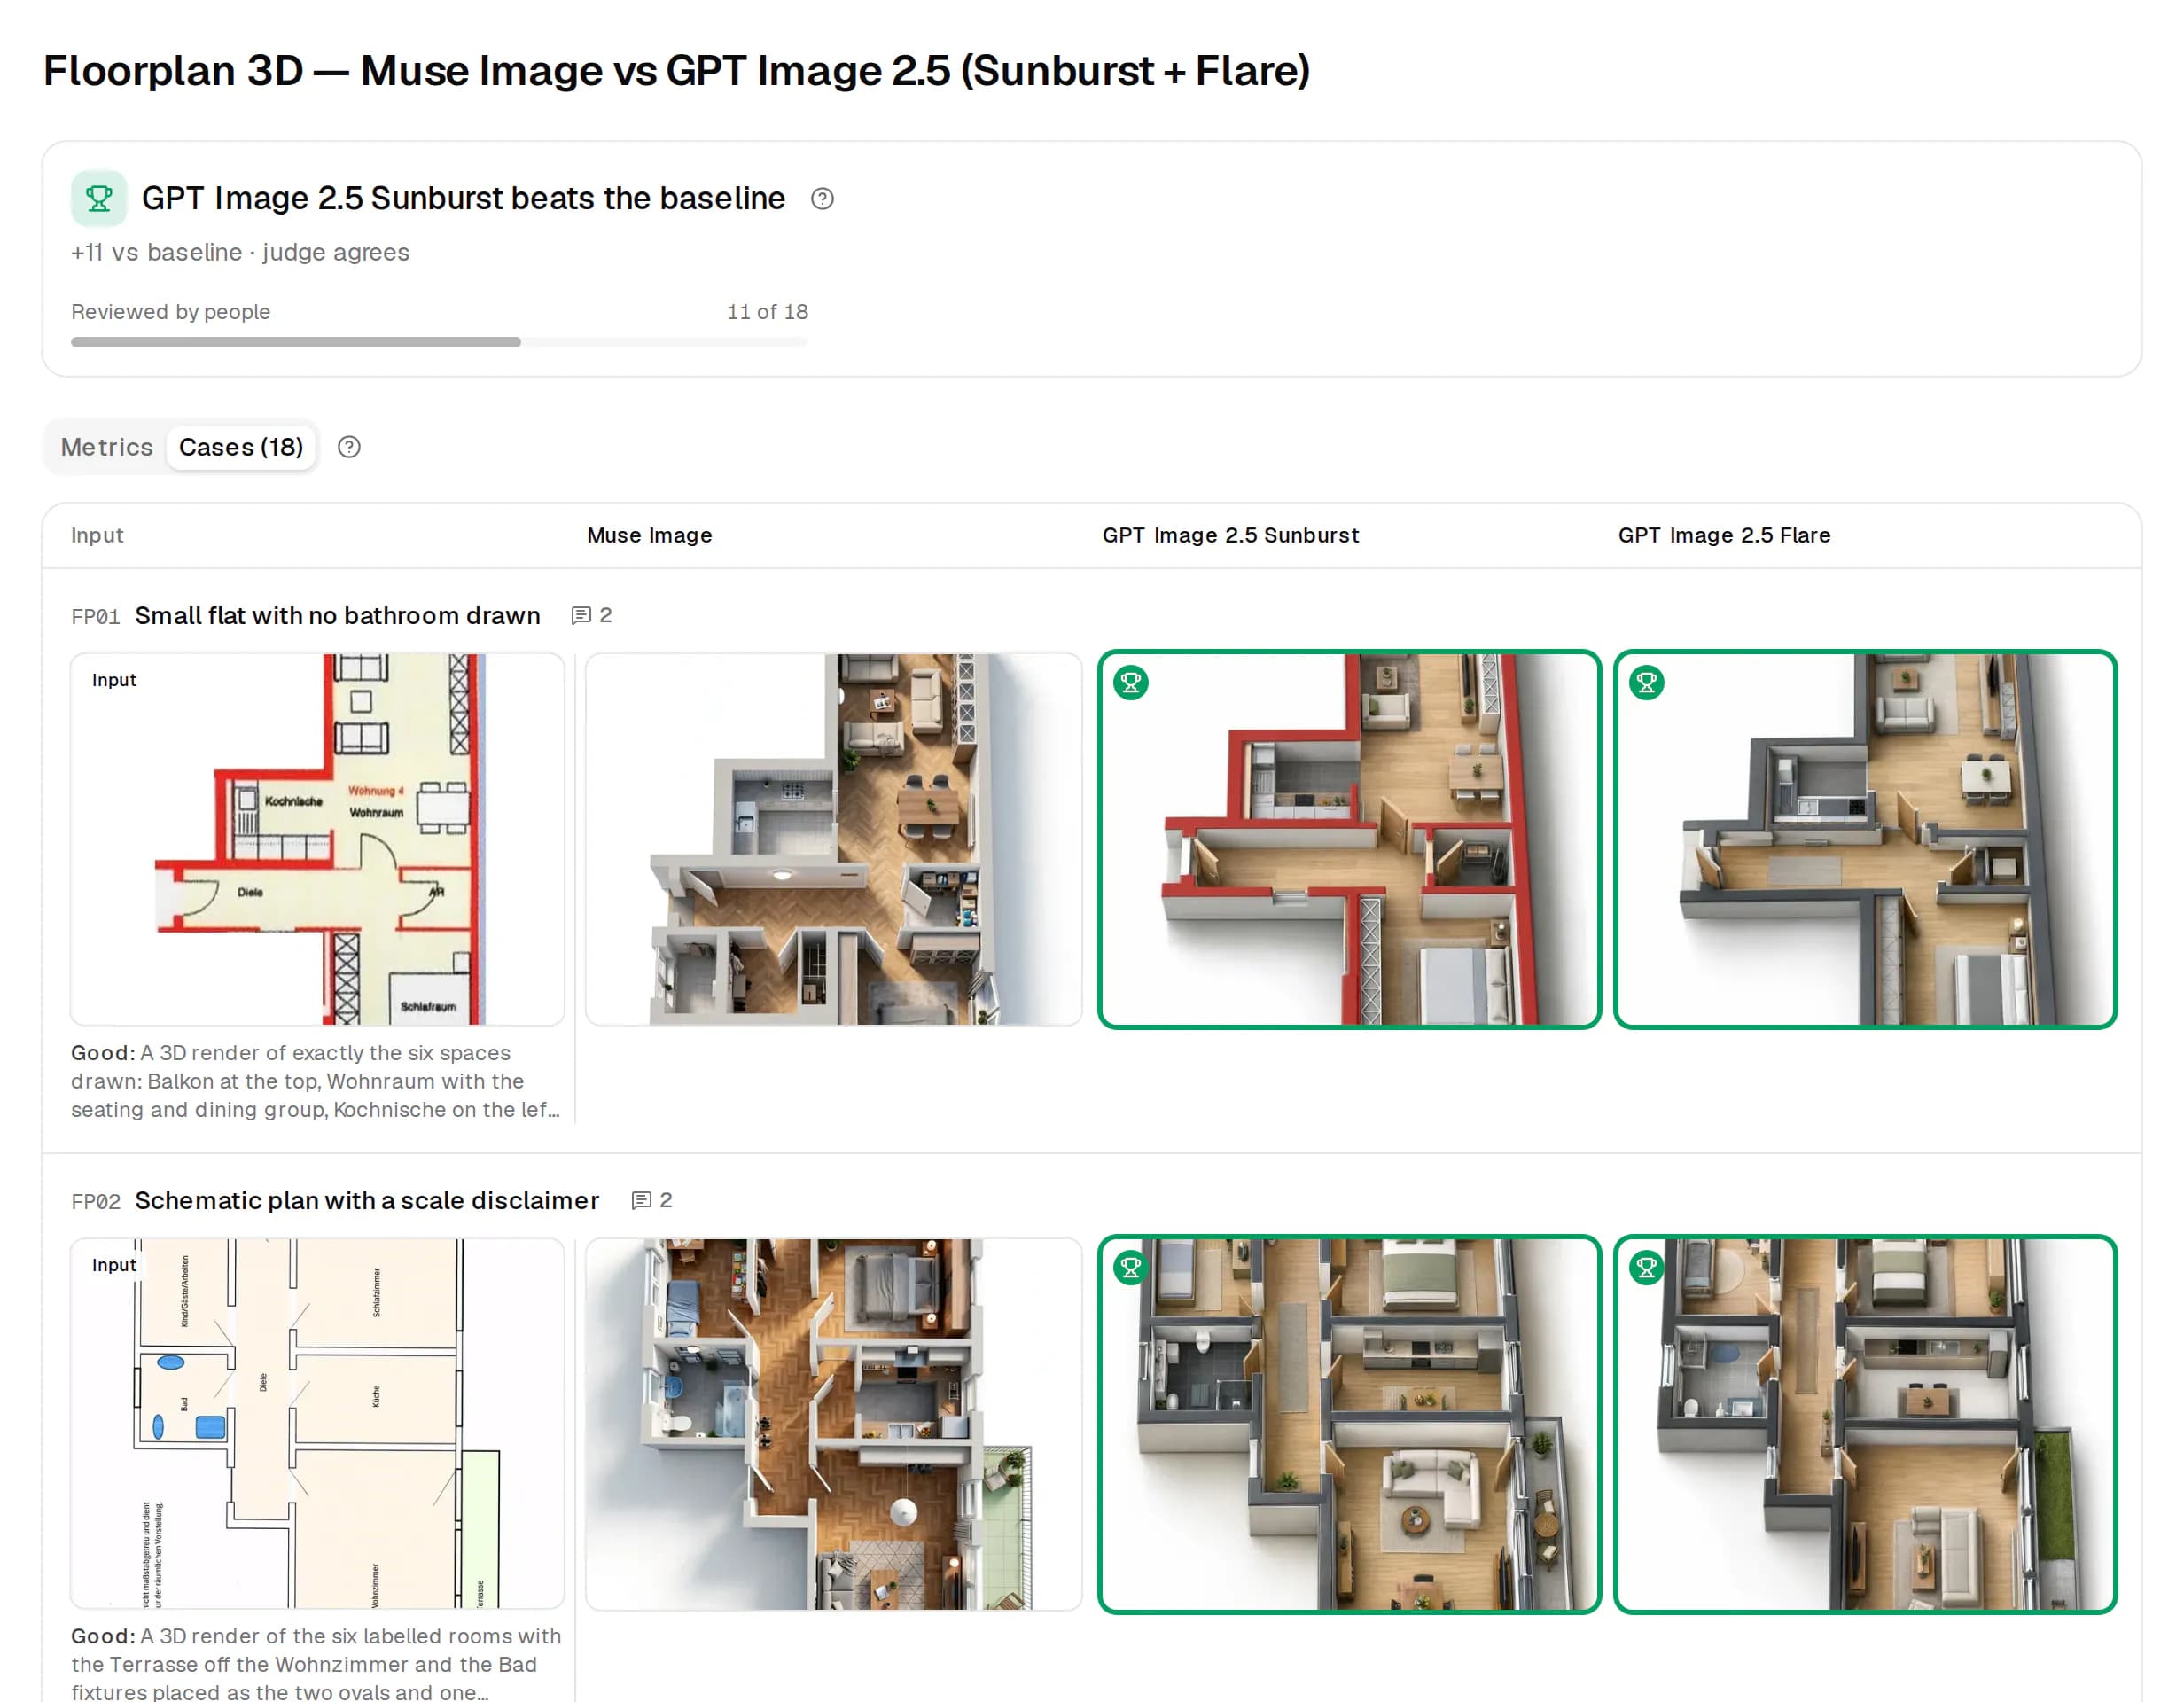
Every case shows each run's output with people's picks, ratings and notes, so you see where a run fails, not only how often.
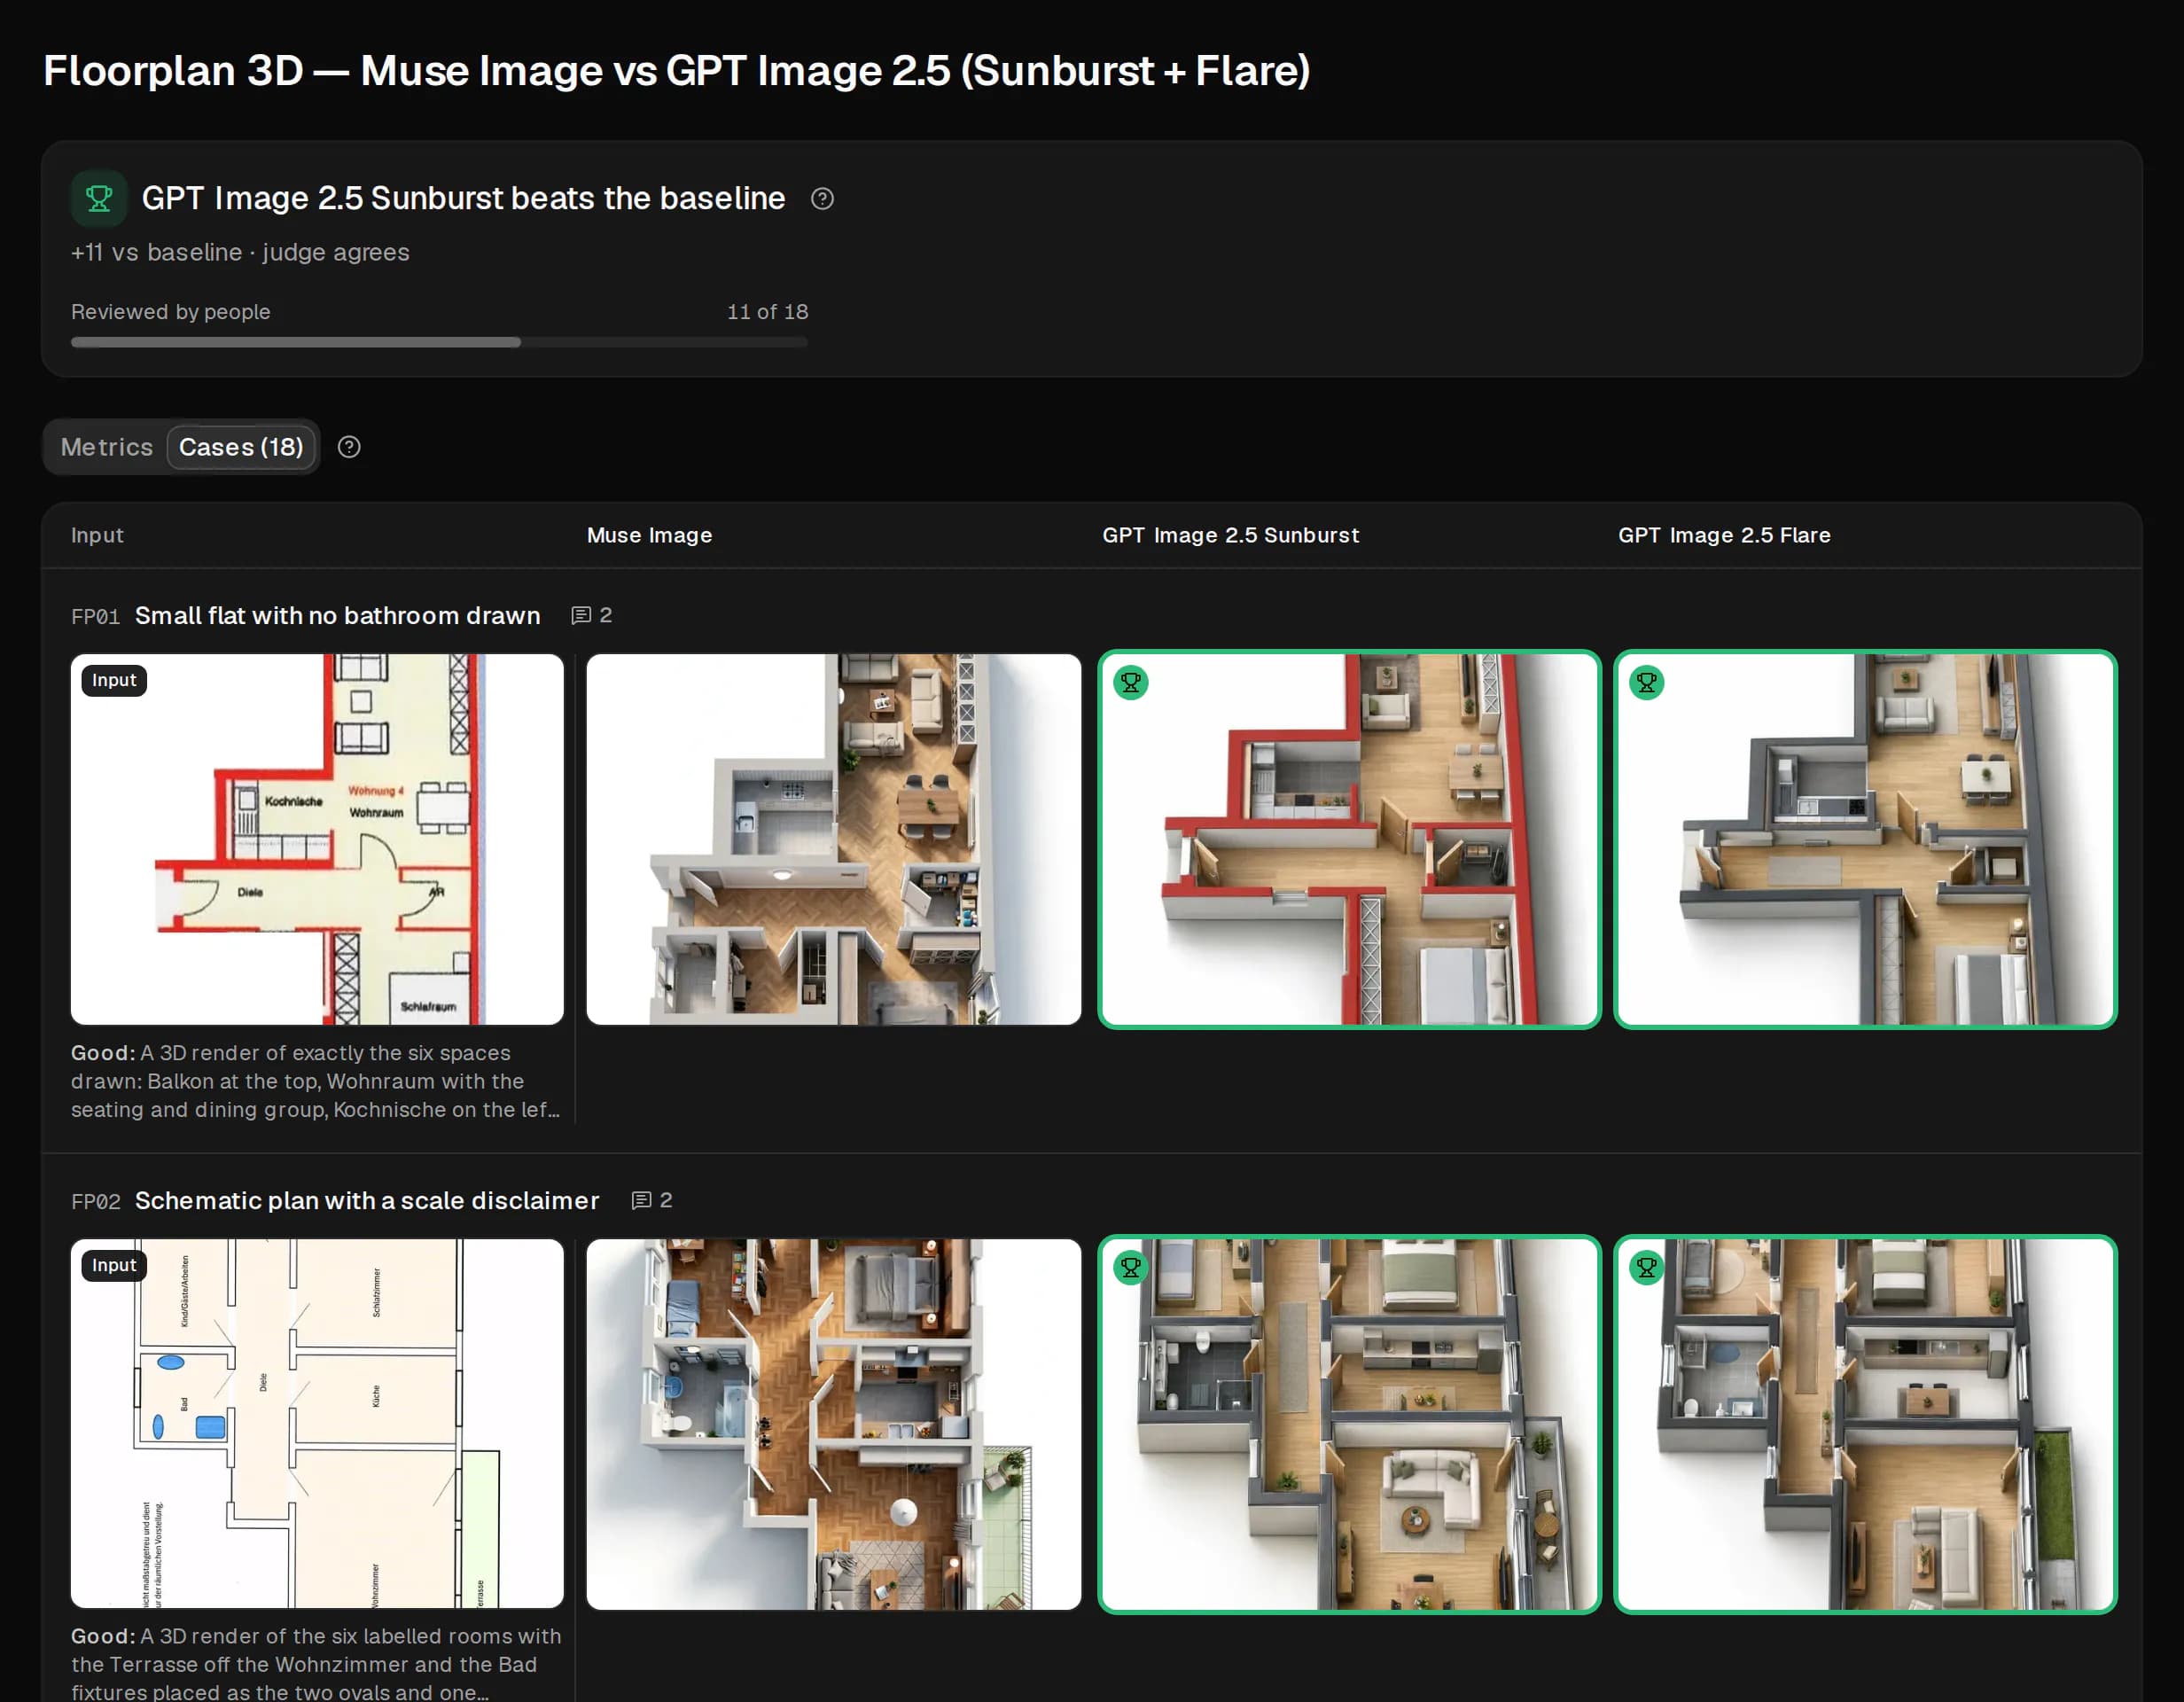
Text and JSON answers too
Answers show as labels, JSON fields or prose next to the expected answer. Send a yes/no score and you get the share right, plus a review of only the wrong ones.
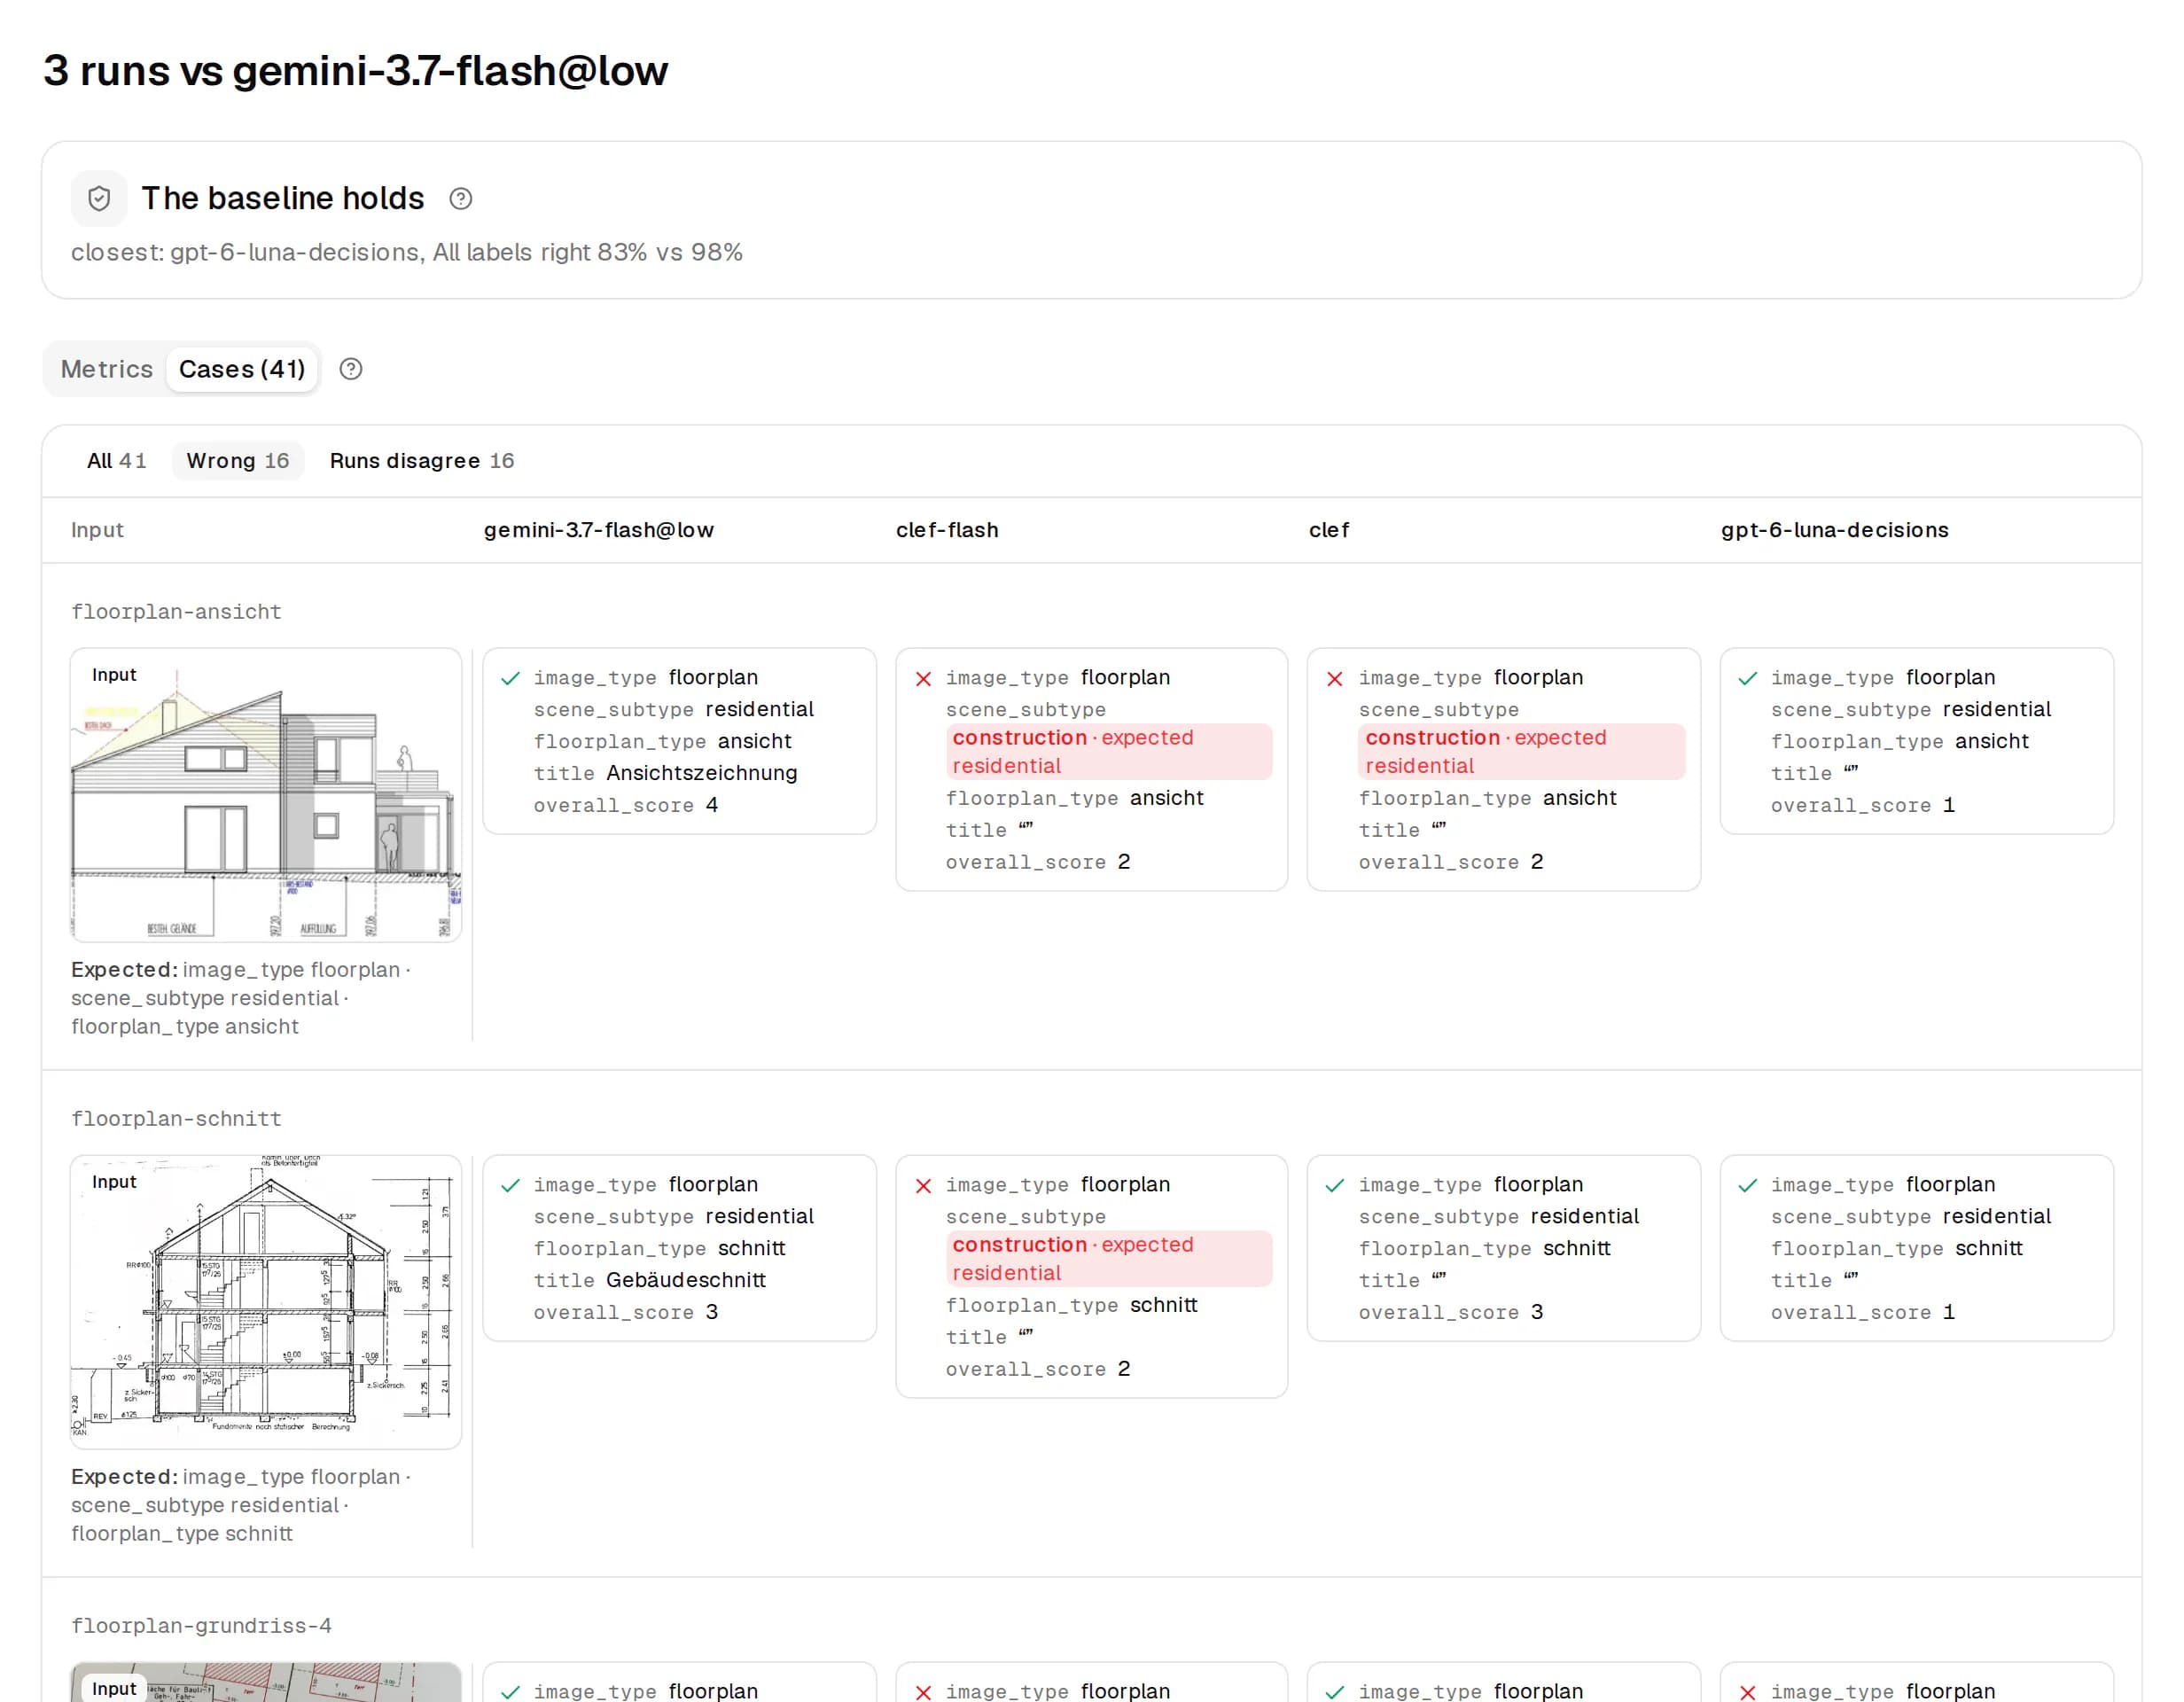
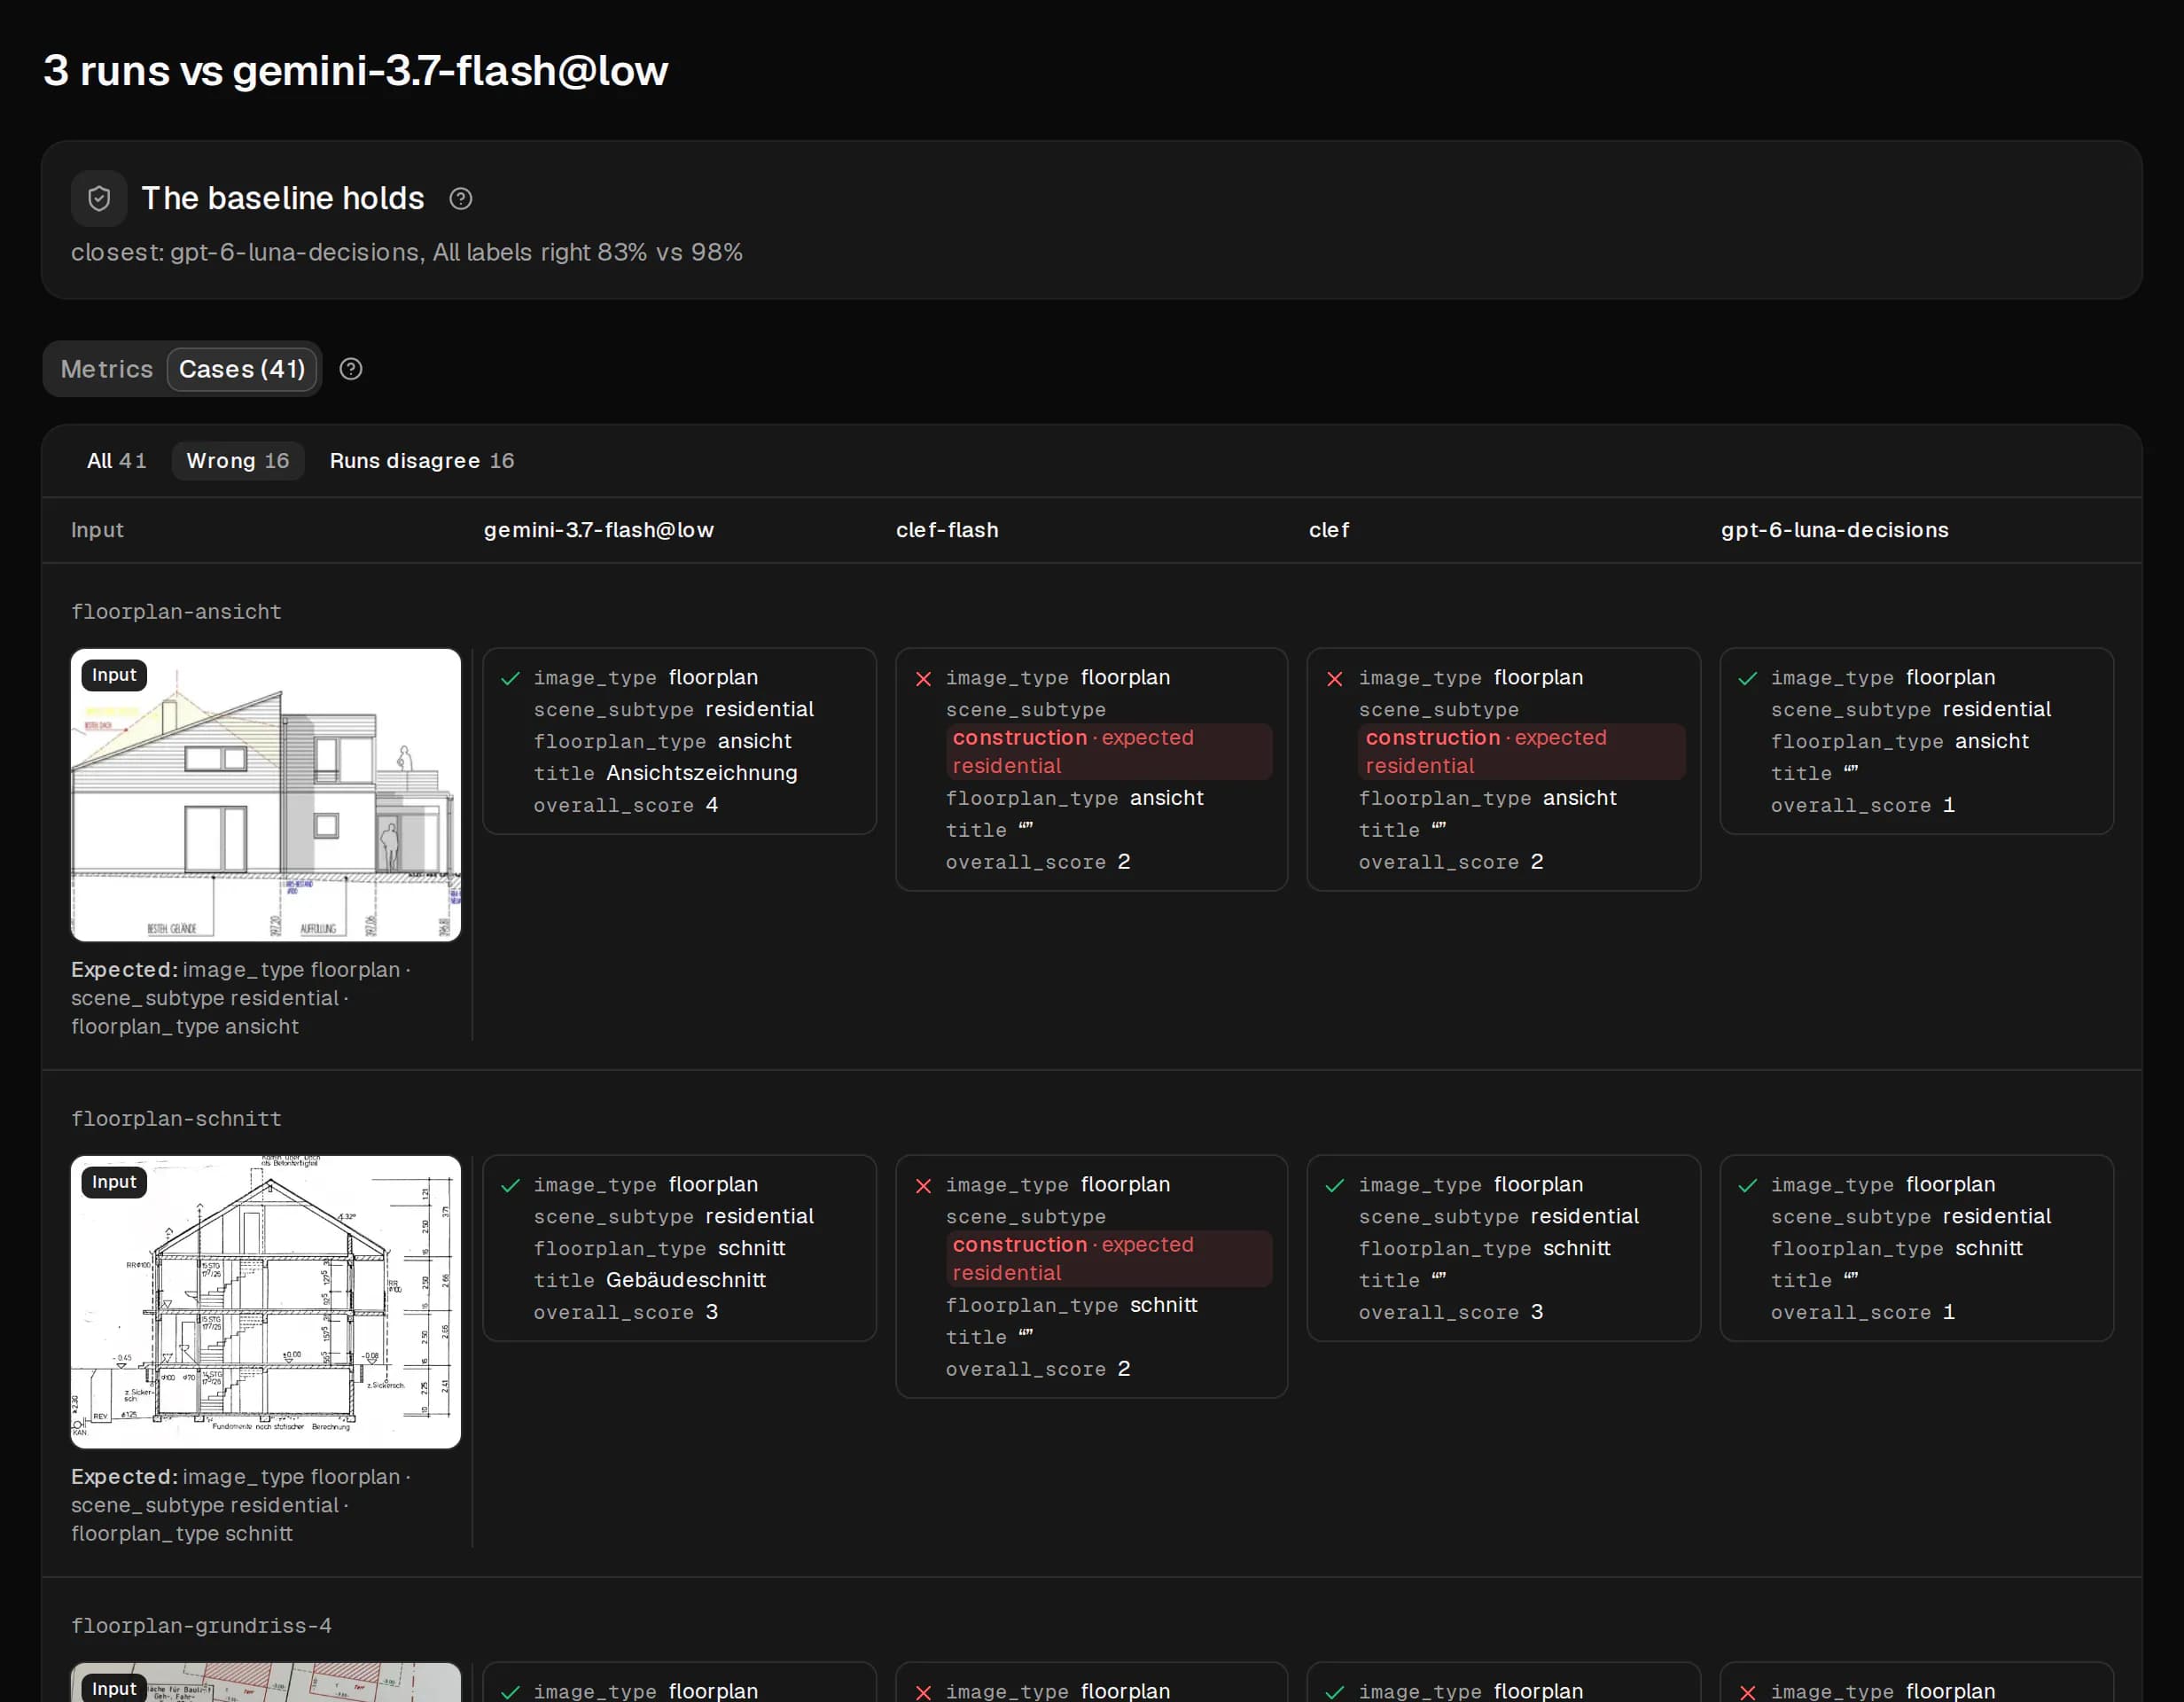
Made for coding agents
Everything works through the API. The agent skill tells Claude Code, Codex and other agents how to upload a run and read your picks and notes before they touch a prompt. Every public page is also available as Markdown.
$ mkdir -p .claude/skills/justevals$ curl -fsSL https://justevals.com/skill.md -o .claude/skills/justevals/SKILL.md$ python justevals.py push manifest.jsonsuite exterior v3 (24 cases, new version)
run Current prompt: 24 outputs -> https://justevals.com/runs/run_…
run Shorter prompt: 24 outputs -> https://justevals.com/runs/run_…$ python justevals.py feedback --suite exterior --batch 2026-10-14-a{
"suite": {
"slug": "exterior",
"version": 3,
"cases": [{"key": "O01", "expected": "Same building, brighter",
"status": "needs_fixing", "status_note": "The mask covers the door"}]
},
"runs": […],
"comparisons": [
{
"case": "O01",
"verdict": "winner",
"winner": {"external_id": "2026-10-14-a:short", "scores": {"judge_score": 4}},
"note": "Keeps the window frames",
"source": "human"
}
],
"reviews": [{"case": "O01", "values": {"score": 4}, "source": "human"}]
}Questions
Does JustEvals run my models?
No. Your pipeline calls the models with your own code and keys, so any model or provider works. JustEvals stores the outputs and what people decided about them. There is no gateway and nothing to proxy.
Is it only for image models?
No. It started with image work, where side-by-side review matters most: the input next to each output, zoom that follows across all of them, and flipping between outputs. Videos play in place. Text, JSON and image-to-text answers show next to the expected answer.
Can automatic scores or an LLM judge decide instead?
Yes. Send your own scores with each output and make one of them the suite's main metric, for example a yes/no score for a correct answer. Picks from an automatic judge show apart from people's picks, so you see where the two disagree.
Does it replace our tracing or observability tool?
No. JustEvals covers evals only: runs, reviews and the feedback on them. Keep your tracing tool for production traffic, and send the eval runs that people should look at to JustEvals.
Why not build our own viewer?
Most teams start that way: a quick HTML page or notebook per eval. It works until you need last month's runs, a second reviewer, or a note your agent can read. JustEvals keeps every run in one place and takes one command from the pipeline you already have.
Where is my data stored?
The app and the database run on a Hetzner server in Nuremberg, Germany. Files are stored in Cloudflare R2 with the EU jurisdiction setting, and the browser loads them through links that expire after one hour. We don't train models on your data, sell it or put it into analytics.
How much does it cost?
JustEvals is in beta, and there is no public price yet. Sign up with the form below, or write to [email protected] with questions.
Updated
Run your next eval through JustEvals
Create an account and your first project, then connect your pipeline with an API key.
- Hosted in the EU
- Private by default
- Your data never trains a model
Questions? Write to [email protected].